2026 New 70-774 Exam Dumps with PDF and VCE Free: https://www.surepassexam.com/70-774-exam-dumps.html
We provide 70-774 Dumps Questions which are the best for clearing 70-774 test, and to get certified by Microsoft Perform Cloud Data Science with Azure Machine Learning (beta). The 70-774 Exam Questions and Answers covers all the knowledge points of the real 70-774 exam. Crack your Microsoft 70-774 Exam with latest dumps, guaranteed!
Online 70-774 free questions and answers of New Version:
NEW QUESTION 1
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this sections, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are designing an Azure Machine Learning workflow.
You have a dataset that contains two million large digital photographs. You plan to detect the presence of trees in the photographs.
You need to ensure that your model supports the following:
Solution: You create a Machine Learning experiment that implements the Multiclass Decision Jungle module. Does this meet the goal?
- A. Yes
- B. No
Answer: B
NEW QUESTION 2
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this sections, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are designing an Azure Machine Learning workflow.
You have a dataset that contains two million large digital photographs.
You plan to detect the presence of trees in the photographs. You need to ensure that your model supports the following:
Solution: You create an Azure notebook that supports the Microsoft Cognitive Toolkit. Does this meet the goal?
- A. Yes
- B. No
Answer: B
NEW QUESTION 3
You have an Execute R Script module that has one input from either a Partition and Sample module or a Web service input module.
You need to preprocess tweets by using R. The solution must meet the following requirements:
How should you complete the R code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar panes or scroll to view content.
NOTE: Each correct selection is worth one point.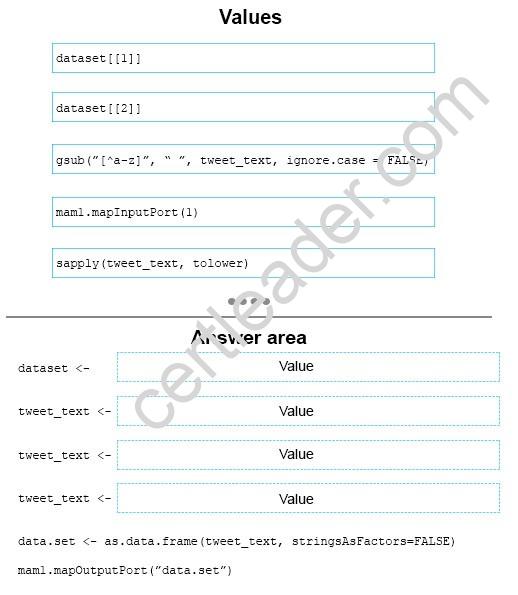
Answer:
Explanation: 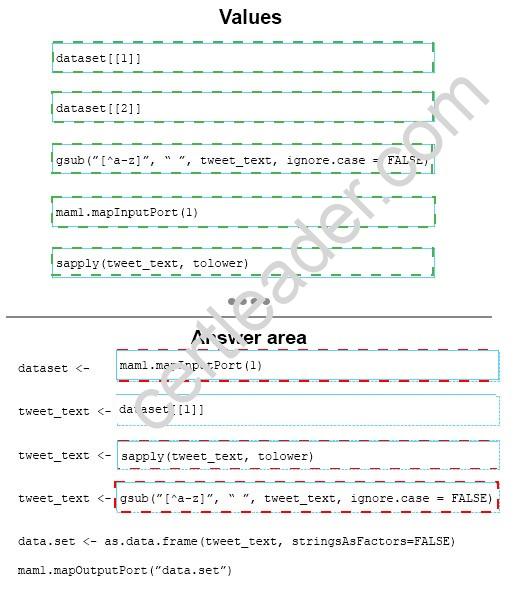
NEW QUESTION 4
You are building an Azure Machine Learning workflow by using Azure Machine Learning Studio. You create an Azure notebook that supports the Microsoft Cognitive Toolkit.
You need to ensure that the stochastic gradient descent (SGD) configuration maximizes the samples per second and supports parallel modeling that is managed by a parameter server.
Which SGD algorithm should you use?
- A. DataParallelASGD
- B. DataParallelSGD
- C. ModelAveragingSGD
- D. BlockMomentumSGD
Answer: C
NEW QUESTION 5
Note: This question is part of a series of questions that use the same scenario. For your convenience, the scenario is repeated in each question. Each question presents a different goal and answer choices, but the text of the scenario is exactly the same in each question in this series.
You plan to create a predictive analytics solution for credit risk assessment and fraud prediction in Azure Machine Learning. The Machine Learning workspace for the solution will be shared with other users in your organization. You will add assets to projects and conduct experiments in the workspace.
The experiments will be used for training models that will be published to provide scoring from web services. The experiment for fraud prediction will use Machine Learning modules and APIs to train the models and will predict probabilities in an Apache Hadoop ecosystem.
You plan to configure the resources for part of a workflow that will be used to preprocess data from files stored in Azure Blob storage. You plan to use Python to preprocess and store the data in Hadoop.
You need to get the data into Hadoop as quickly as possible.
Which three actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
- A. Create an Azure virtual machine (VM), and then configure MapReduce on the VM.
- B. Create an Azure HDInsight Hadoop cluster.
- C. Create an Azure virtual machine (VM), and then install an IPython Notebook server.
- D. Process the files by using Python to store the data to a Hadoop instance.
- E. Create the Machine learning experiment, and then add an Execute Python Script module.
Answer: BDE
NEW QUESTION 6
You are performing exploratory analysis of files that are encoded in a complex proprietary format. The format requires disk intensive access to several dependent files in HDFS.
You need to build an Azure Machine Learning model by using a canopy clustering algorithm. You must ensure that changes to proprietary file formats can be maintained by using the least amount of effort.
Which Machine Learning library should you use?
- A. MicrosoftML
- B. scikit-learn
- C. SparkR
- D. Mahout
Answer: C
NEW QUESTION 7
Note: This question is part of a series of questions that use the same scenario. For your convenience, the scenario is repeated in each question. Each question presents a different goal and answer choices, but the text of the scenario is exactly the same in each question in this series.
Start of repeated scenario
You plan to use Azure platform tools to detect and analyze food items in smart refrigerators. To provide families with an integrated experience for grocery shopping and cooking, the refrigerators will connect to other smart appliances, such as stoves and microwave ovens, on a LAN.
You plan to build an object recognition model by using the Microsoft Cognitive Toolkit. The object recognition model will receive input from the connected devices and send results to applications.
The training data will be derived from more than 10 TB of images. You will convert the raw images to the sparse format.
End of repeated scenario.
You need to deploy a multiple-service solution that was developed already and published by other users in the Microsoft development community.
What should you use?
- A. the edX Data Science Learning Dashboard
- B. the Data Science Virtual Machine
- C. an Azure Machine Learning experiment
- D. Cortana Intelligence Gallery
Answer: C
NEW QUESTION 8
You deploy Microsoft Data Management Gateway.
You plan to use the Import Data module in Azure Machine Learning Studio to import data from an on-premises Microsoft SQL Server instance.
Which operation can you perform?
- A. Write the data back to the on-premises SQL Server instance.
- B. Filter the data as the data is being read by using the Import Data module.
- C. Run a Transact-SQL query and use SQL views to filter the data as the data is being read.
- D. Access the on-premises SQL Server instance without using credentials, and then import the data.
Answer: D
NEW QUESTION 9
You need to integrate code and formatted text into an Azure Machine Learning experiment that enables interactive execution.
What should you use?
- A. a Jupyter notebook
- B. Azure Stream Analytics
- C. an Execute Python Script module
- D. an Execute R Script module
Answer: A
NEW QUESTION 10
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this sections, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are designing an Azure Machine Learning workflow.
You have a dataset that contains two million large digital photographs. You plan to detect the presence of trees in the photographs.
You need to ensure that your model supports the following: Solution: You create an endpoint to the Computer vision API. Does this meet the goal?
- A. Yes
- B. No
Answer: B
NEW QUESTION 11
You have data about the following:
• Users
• Movies
• User ratings of the movies
You need to predict whether a user will like a particular movie. Which Matchbox recommender should you use?
- A. Rating Prediction
- B. Related Users
- C. Item Recommendation
- D. Related Items
Answer: A
NEW QUESTION 12
Note: This question is part of a series of questions that use the same scenario. For your convenience, the scenario is repeated in each question. Each question presents a different goal and answer choices, but the text of the scenario is exactly the same in each question in this series.
A travel agency named Margie’s Travel sells airline tickets to customers in the United States.
Margie’s Travel wants you to provide insights and predictions on flight delays. The agency is considering implementing a system that will communicate to its customers as the flight departure nears about possible delays due to weather conditions. The flight data contains the following attributes:
The weather data contains the following attributes: AirportID, ReadingDate (YYYY/MM/DD HH), SkyConditionVisibility, WeatherType, WindSpeed, StationPressure, PressureChange, and HourlyPrecip.
You have an untrained Azure Machine Learning model that you plan to train to predict flight delays.
You need to assess the variability of the dataset and the reliability of the predictions from the model. Which module should you use?
- A. Cross-Validate Model
- B. Evaluate Model
- C. Tune Model Hyperparameters
- D. Train Model
- E. Score Model
Answer: A
Explanation: References:
https://msdn.microsoft.com/en-us/library/azure/dn905852.aspx
NEW QUESTION 13
You have an Apache Spark cluster in Azure HDinsight. The cluster includes 200 TB in five Apache Hive tables that have multiple foreign key relationships.
You have an Azure Machine Learning model that was built by using SPARK Accelerated Failure Time (AFT) Survival Regression Model (spark-survreg).
You need to prepare the Hive data into a single table as input for the Machine Learning model. The Hive data must be prepared in the least amount of time possible.
What should you use to prepare the data?
- A. a Hive user-defined function (UDF)
- B. Spark SQL
- C. the GPU
- D. Java Mapreduce jobs
Answer: A
NEW QUESTION 14
You are building an Azure Machine Learning experiment.
You need to transform a string column that has 47 distinct values into a binary indicator column. The solution must use the One-vs-All Multiclass model.
Which module should you use?
- A. Select Column Transform
- B. Convert to Indicator Values
- C. Group Categorical Values
- D. Edit Metadata
Answer: B
NEW QUESTION 15
Note: This question is part of a series of questions that use the same or similar answer choices. An answer choice may be correct for more than one question in the series. Each question is independent of the other questions in this series. Information and details provided in a question apply only to that question.
You need to transform the columns in a dataset. The resulting data must be mean centered and have a variance of L The solution must use a native module.
Which module should you use?
- A. Execute Python Script
- B. Import Data
- C. Edit Metadata
- D. Select Columns in Dataset
- E. Clean Missing Data
- F. Tune Model Hyperparameters
- G. Clip Values
- H. Normalize Data
Answer: H
NEW QUESTION 16
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure ML experiment that contains an intermediate dataset. You need to explore data from the intermediate dataset by using Jupyter.
Solution: You add a Convert to ARFF module, and then add the Execute R Script module. Does this meet the goal?
- A. Yes
- B. No
Answer: B
NEW QUESTION 17
You have the following three training datasets for a restaurant:
You must recommend restaurant to a particular user based only on the users features. You need to use a Matchbox Recommender to make recommendations.
How many input parameters should you specify?
- A. 1
- B. 2
- C. 3
- D. 4
Answer: B
Explanation: References:
https://msdn.microsoft.com/en-us/library/azure/dn905987.aspx
P.S. 2passeasy now are offering 100% pass ensure 70-774 dumps! All 70-774 exam questions have been updated with correct answers: https://www.2passeasy.com/dumps/70-774/ (64 New Questions)